

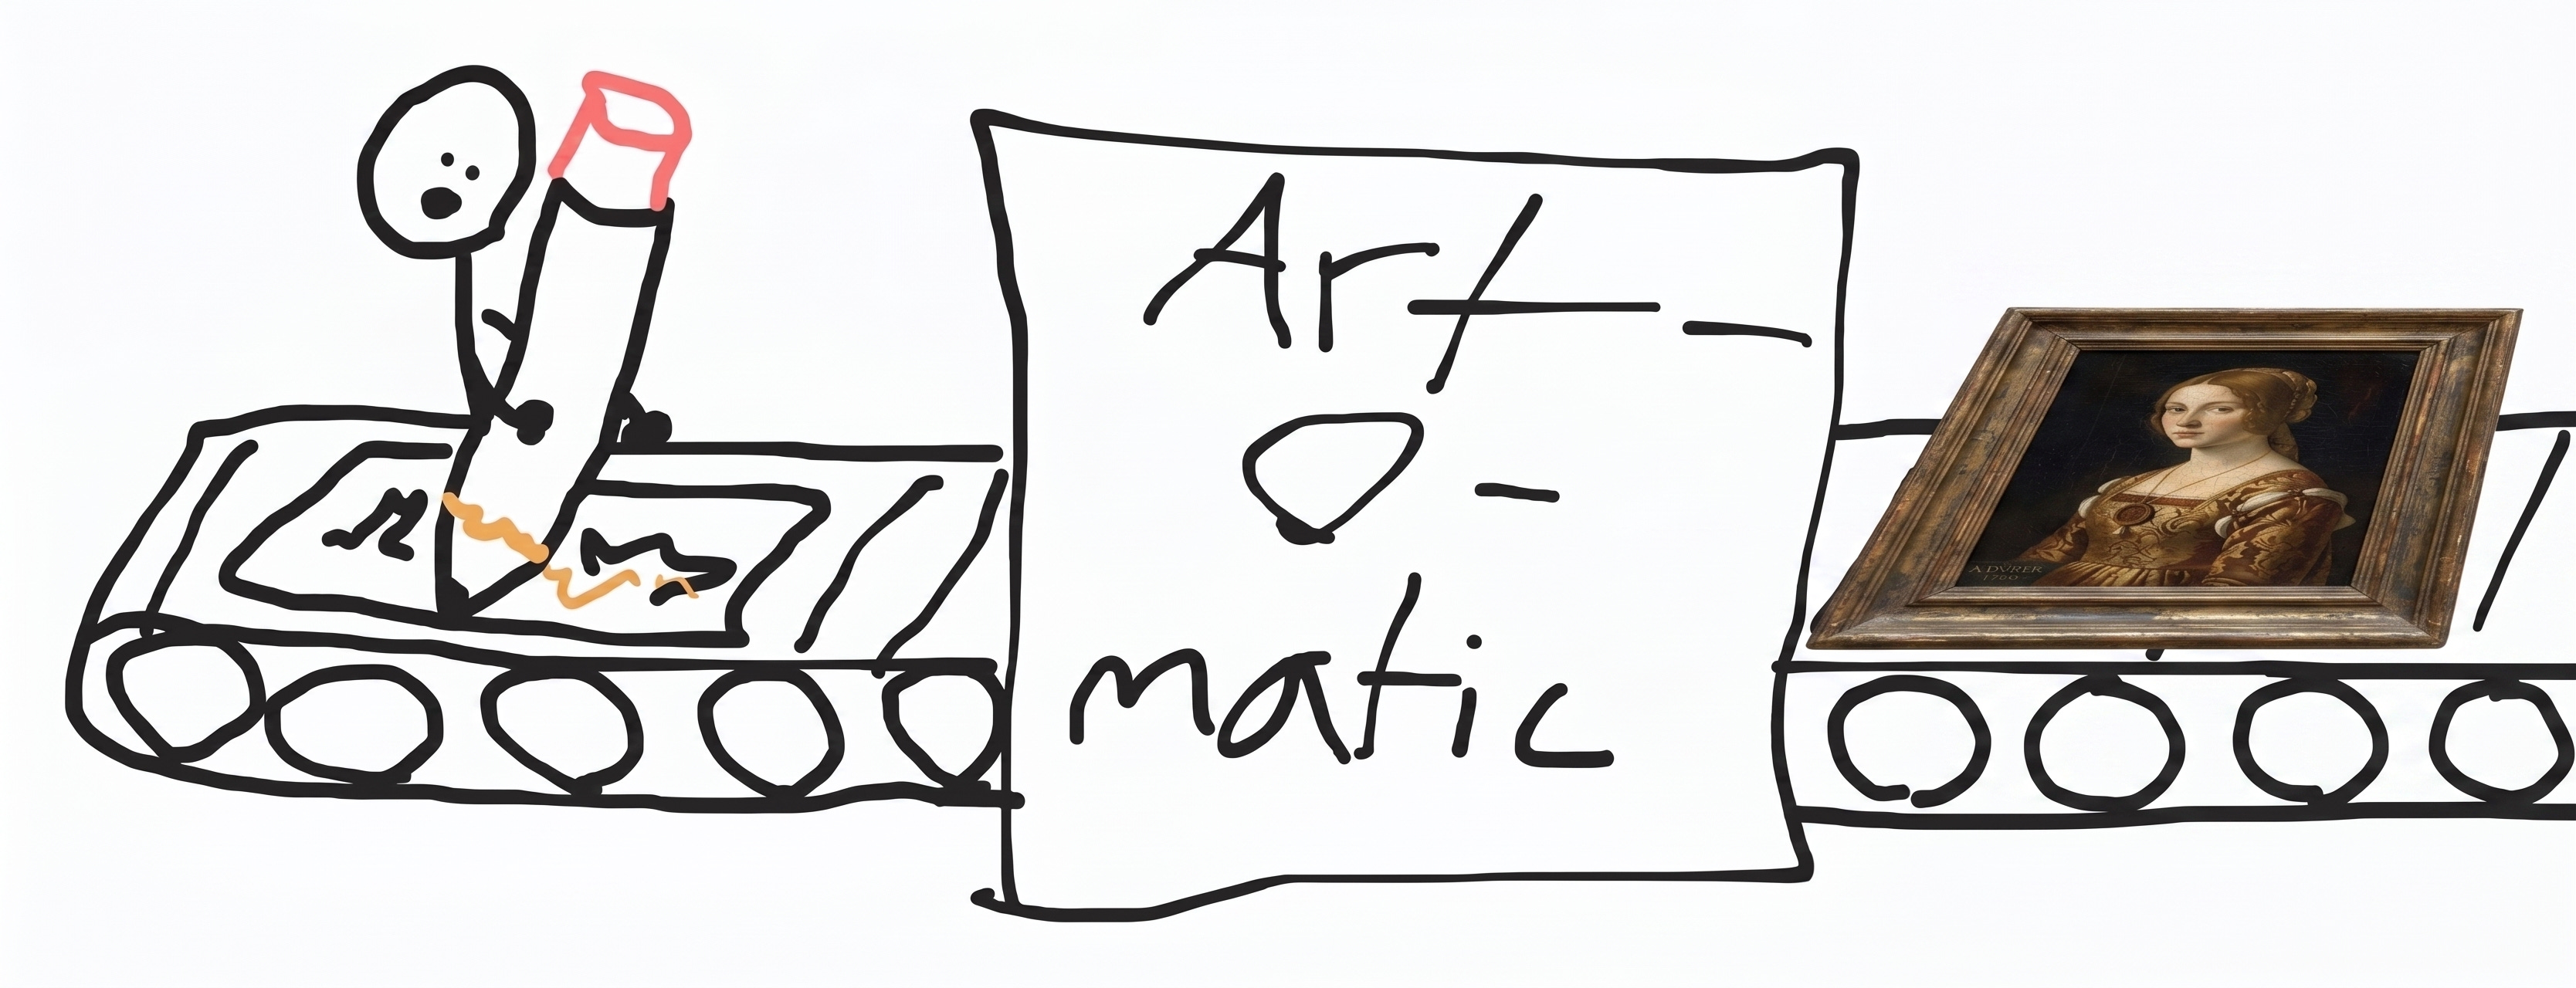
Here’s a meme I posted today on X:


I figured I’d share my workflow for generating the above image, since I think it demonstrates how putting in a little human effort can help you get an output that’s much closer to what you want.
For this meme, I had a vision. I could see in my head exactly what shape I wanted the image to take, but I didn’t have the artistic skill to create it myself.
So I opened up tl;draw and drew a very crude concept sketch. If you haven’t used tl;draw before, it’s a free online drawing app that gives you some simple drawing tools and an infinite canvas right in your web browser.
But you don’t have to use tl;draw! I could just as easily have used Microsoft Paint or even taken a cell phone photograph of a drawing on a napkin. It’s all the same idea.
Anyway, here’s what I drew:
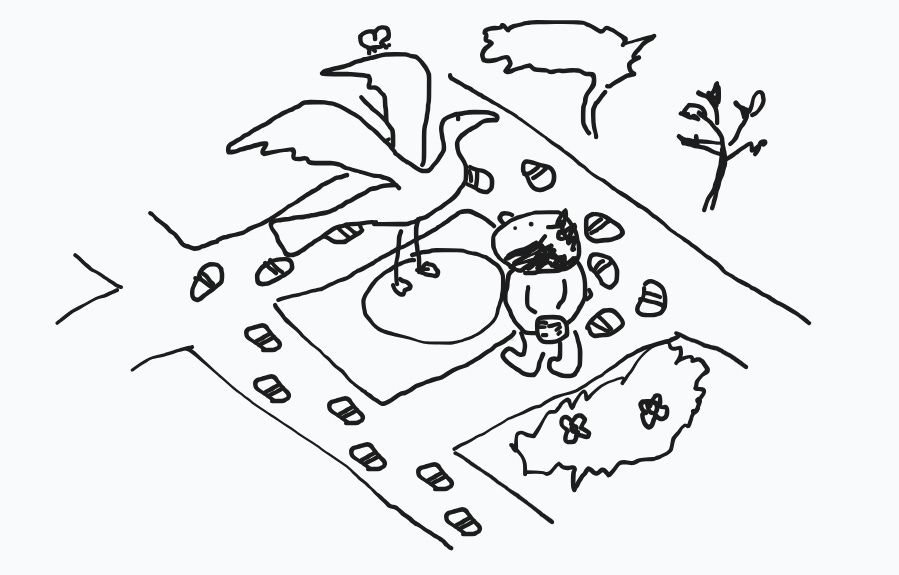
You can export a sketch to file from tl;draw by clicking the “Share” button and then clicking the “Export” tab.
Once I had my image, I navigated over to Google Gemini and opened a “New Chat”. (You will likely need a subscription for this, although they may have a free trial.) In the chat box, there’s a “plus” icon that will open a dropdown menu. From that menu, you can select “Create image” to put Gemini in image generation mode.
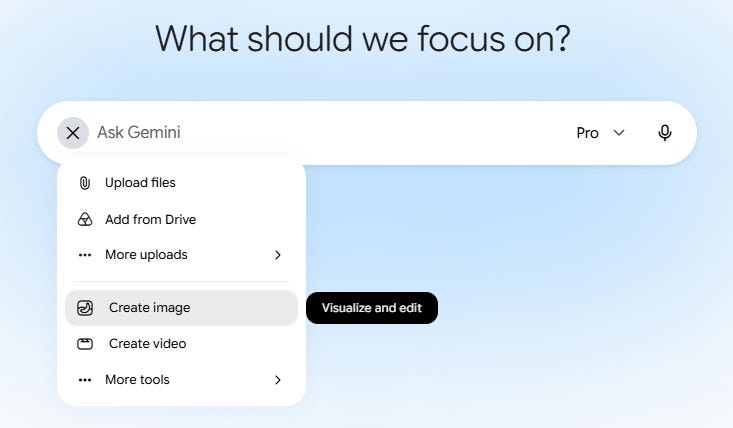
With that selected, the ordinary workflow would be to verbally describe what you want. But the underappreciated superpower of Gemini’s image generator is that you can combine verbal prompts with uploaded image prompts to help visually steer the model toward the shape or style you want. Just click the menu again, and select “Upload files”. You can upload more than one!
In this case, I used:
My hand-drawn tl;draw sketch,
An uploaded image of children’s book cover that illustrated the style I wanted, and
A natural language prompt:
Here’s my very crude concept sketch for a scene in which a child has walked through a transquil Japanese garden in winter, leaving small footprints on the snowy garden path that show her circumambulatory route. She has paused before a statue of a pelican taking flight and is gazing up at it with hands clasped behind her back. A butterfly alights atop the pelican’s wings. Japanese pen and ink watercolor, stubby large-headed figure in the style of the children’s book Little Nippon.
Note that I didn’t try to add the internal “aaa!” thought trail from the meme just yet. I was already asking a lot of the model, and I didn’t want to overwhelm its attention with requirements.
The output I got back from Gemini was pretty close to what I wanted, but it had some problems. There are two extra sets of footprints that deviate from the walking path I specified in my sketch, and there’s also a section of footprints where the orientation is reversed.
Now, Gemini has tools for fixing this. You can give the model verbal instructions about what edits to make, and it will try to make them. Also, if you click and zoom the image, they give you drawing tools so you can add markup to help steer the model. In this case, I circled in red the footprints I wanted removed, and in blue the ones I wanted reversed, and I told the model in a text prompt what to do in each circled region.
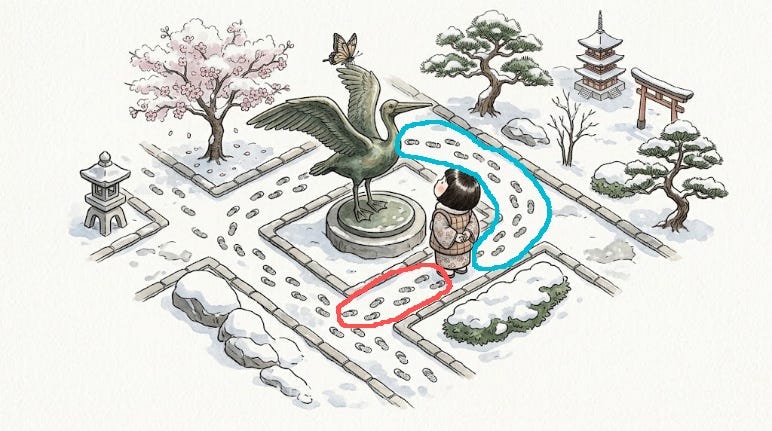
I’ll be honest, though; this doesn’t work very well. Gemini did make the requested changes, but it also added a new set of extra footprints exiting the garden to the right. Also, I felt that the quality of the image was reduced after this second pass.
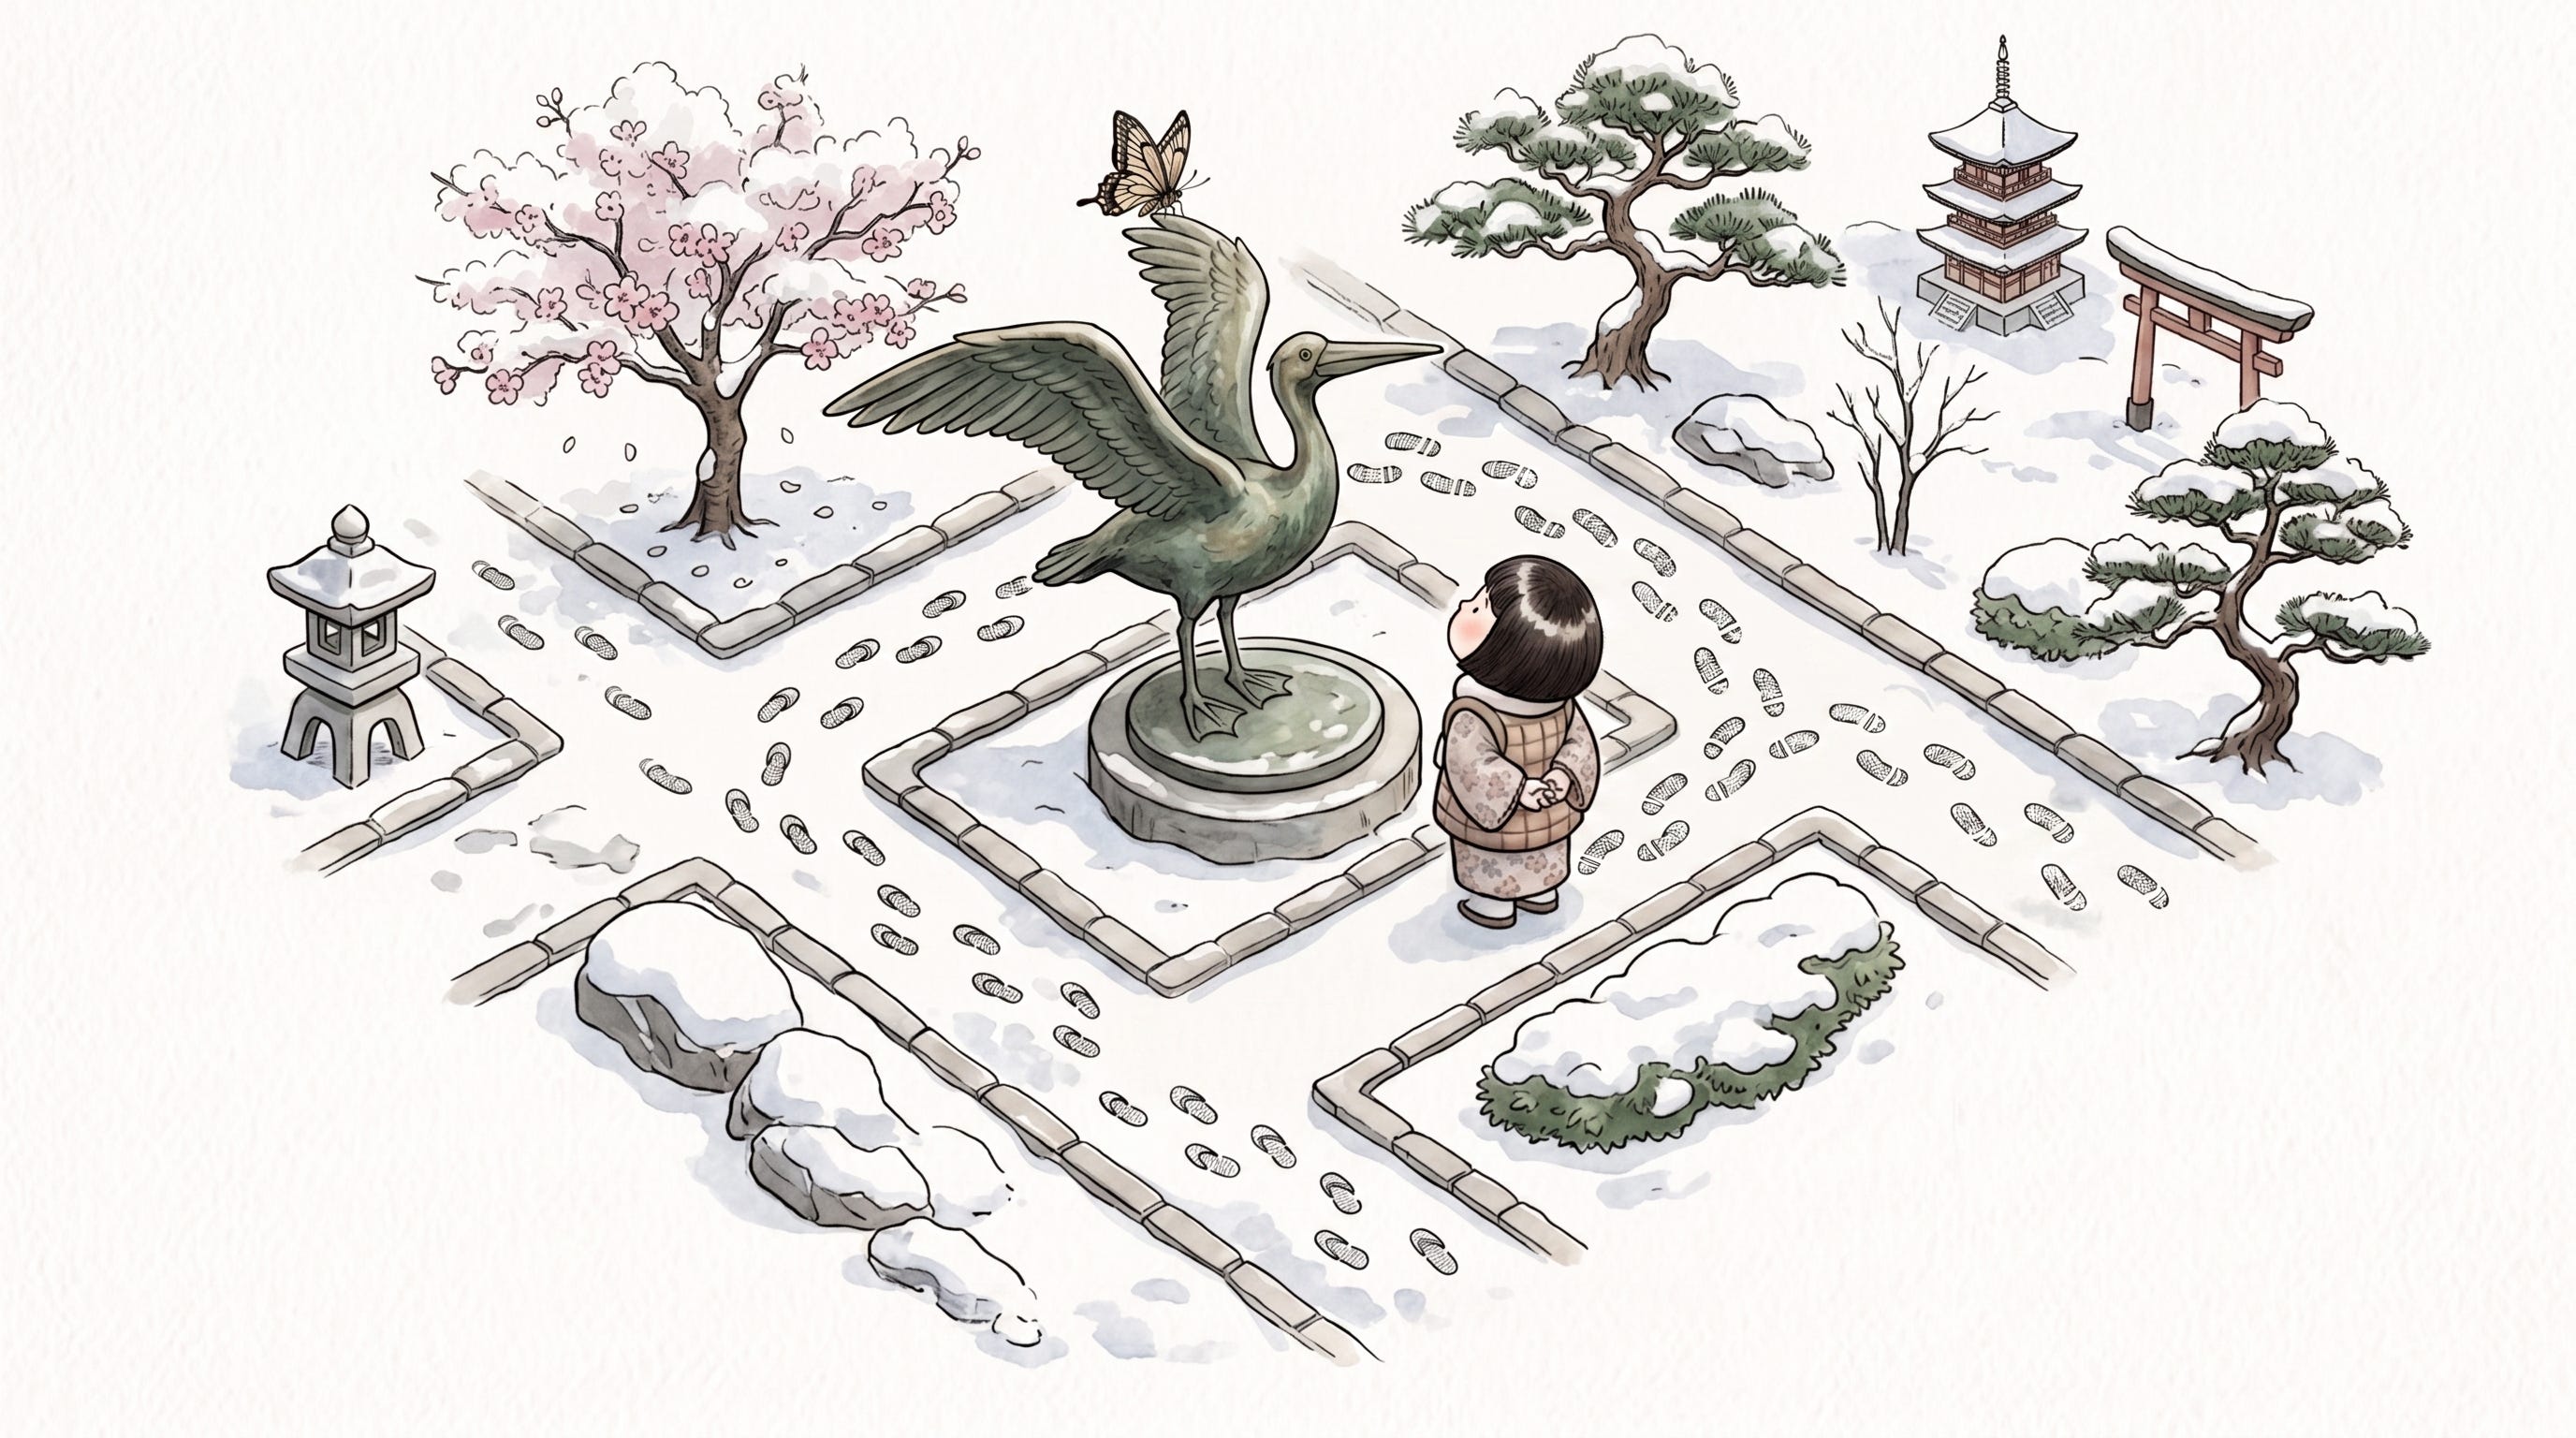
So instead of using the Gemini-edited image, I opened up an open-source image editor called GIMP and used its clone tool to remove the footprints I didn’t want. (I could have also flipped the orientation of the footprints in the blue-circled area, but decided it wasn’t worth the trouble to manually edit.) And finally, I also used GIMP to add my text and to crop out some image features that felt a little too culturally stereotyped for my comfort level.
Here’s the final version, which represents a mixture of machine and human effort:
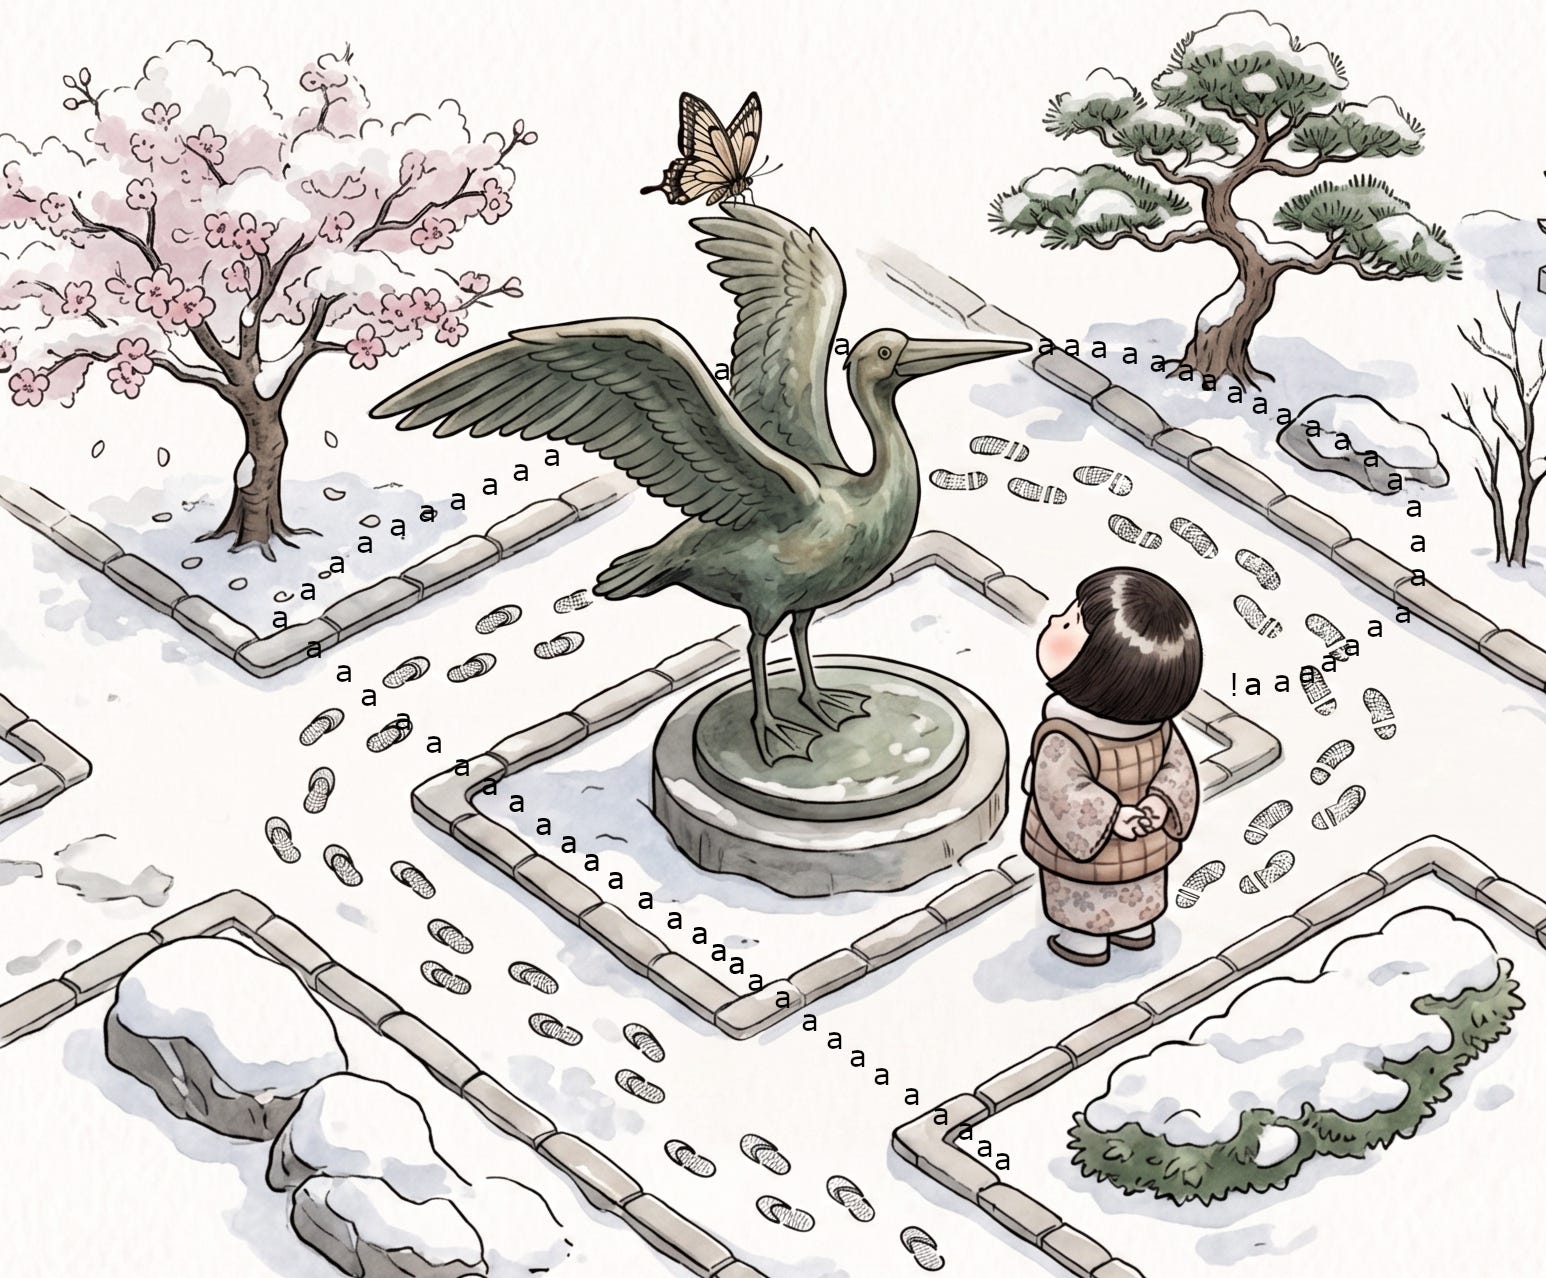
Note: it used to be the case that image models were very bad at text. That has changed somewhat, and Gemini is pretty good at it now! But I had a pretty specific vision of how I wanted the text arranged visually on the image, and, like I said, the quality seems to get reduced with each AI editing pass. So I think it’s worth making simple/easy edits manually instead, if you have some graphic design tools and know what you’re doing with them.
Besides, your audience will appreciate if you put in a little human elbow grease now and then rather than letting a machine do all the work!
This was very informative. I saw this meme but didn't realize that you created it. I also had no idea how much work went into it. Thanks for sharing the process.